

We’ve all been there: you spend a week at an archive taking hundreds, if not thousands, of photos of documents. It’s a great trip: there’s so much useful material for your research, and while you’ve been jotting down notes as you go, you’re going to need to dive into the photos to get everything you need. But first you need to get back to revising that article your reviewers just sent back, or finish grading those final exams. By the time you’re ready to dive into your archival haul a few weeks later, you find yourself staring at a folder of 1,000 jpegs while a pit of anxiety forms in your stomach.
There are many tools out there to help manage this situation. Some historians process each document as they go in the archive—though many of us don’t have the luxury of the time this requires. Others use Tropy, an open-source app designed explicitly for organizing research photos. But Tropy lacks built-in OCR, and still requires you to manually group photos of multi-page documents together and add essential metadata, like authorship and year. I started my dissertation using a modified version of Elena Razlogova’s Zotero workflow for the archive, which allows me to add OCR-ed scans of typed archival documents that can easily be tagged, organized, and cited alongside my library of secondary sources. But doing this one document at a time, whether at home or in the archive as I go, is time-consuming. I wish I was a tenured Ivy League professor with a research assistant who could do all this grunt work: grouping photos by document, and saving each document in a database with its title, author, date, type, and citation information, so I could jump into the fun part: actually reading the documents and understanding what they add to my project.
Well, I’m still a lowly PhD candidate, but I have found a research assistant who can do all this work for me, at a shockingly low price of $20/month. His name is Claude.
My AI-enhanced archive workflow
As this Substack has shown, LLMs are not a good substitute for the historian’s essential functions of close reading, critical analysis, and writing. But for extracting structured data from images, they have become quite excellent, and very cost-effective. My archive workflow, diagramed below, takes advantage of this division of labor:
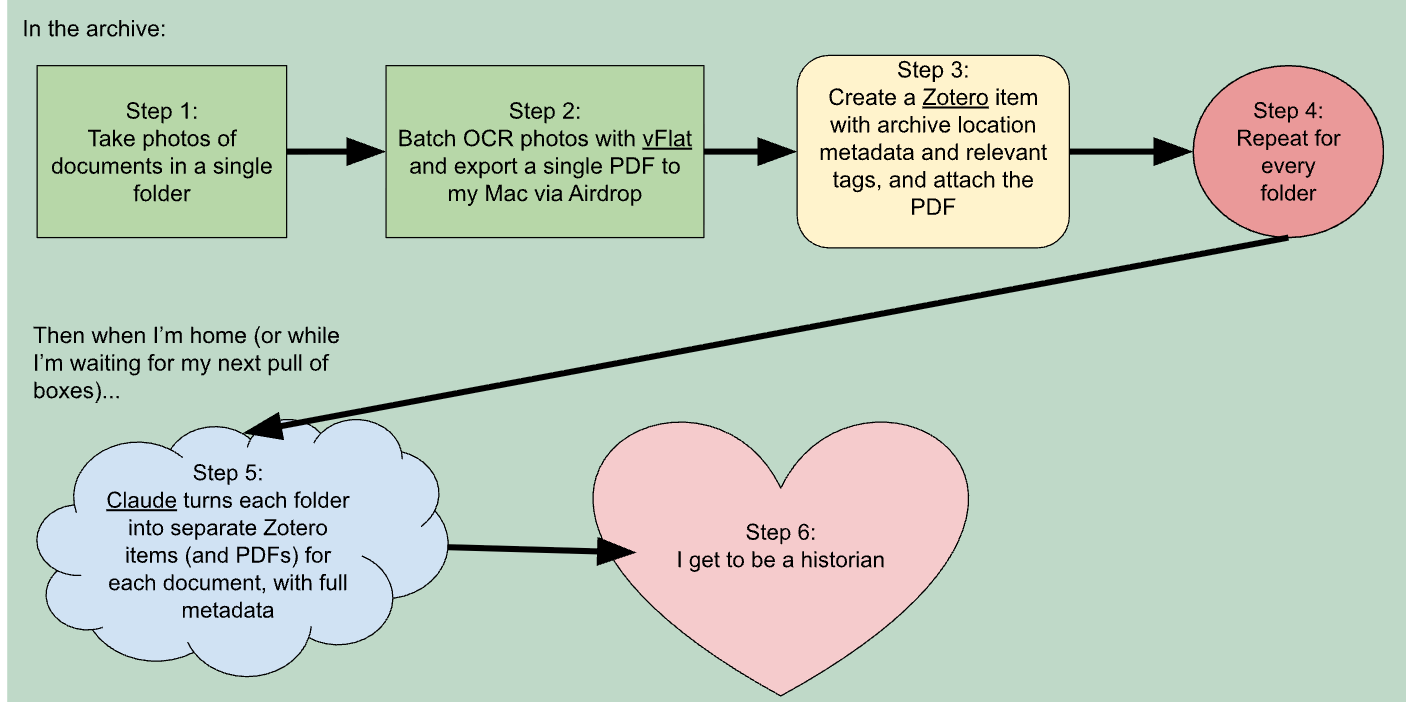
I’ll go through this workflow, step-by-step, but first, a few caveats: This workflow is tailored to me, and you will likely want to modify it for your needs (especially if, for example, the archival material you work with is mainly images or handwritten documents). You also don’t need to use the same apps I use, and you can even have AI just take raw photos from your phone directly and import them into Zotero. And if you want to see how I set up Claude to do just the AI portion of this, skip to Step 5.
Steps 1 and 2: Scan documents + OCR
I’m at the New York State Archives, looking at the Comptroller’s Subject File series. I’ve opened box 64 and pulled out folder 1. There’s a bunch of useful material for my chapter on pension funds and private equity. Time to get scanning.
I scan documents with the iPhone/Android app vFlat: for $4/month it offers automatic adjustment for color, shadows, and even page curvature (essential when I’m working with bound magazine volumes), can do 1 or 2 page mode, and has built-in OCR. But you could just as easily use Adobe Scan or the Camera app. OCR’ing at this stage is also optional–you could do it on your laptop, in Zotero with an extension, or even have the AI do it in Step 5.
After scanning the whole folder, I select all the images in vFlat and choose the “Export to PDF” option. I Airdrop the file to my laptop. Again, you don’t even have to make your images a PDF at this stage. You could just copy the JPEGs to a folder on your computer.
Step 3: Create Zotero item for folder scan
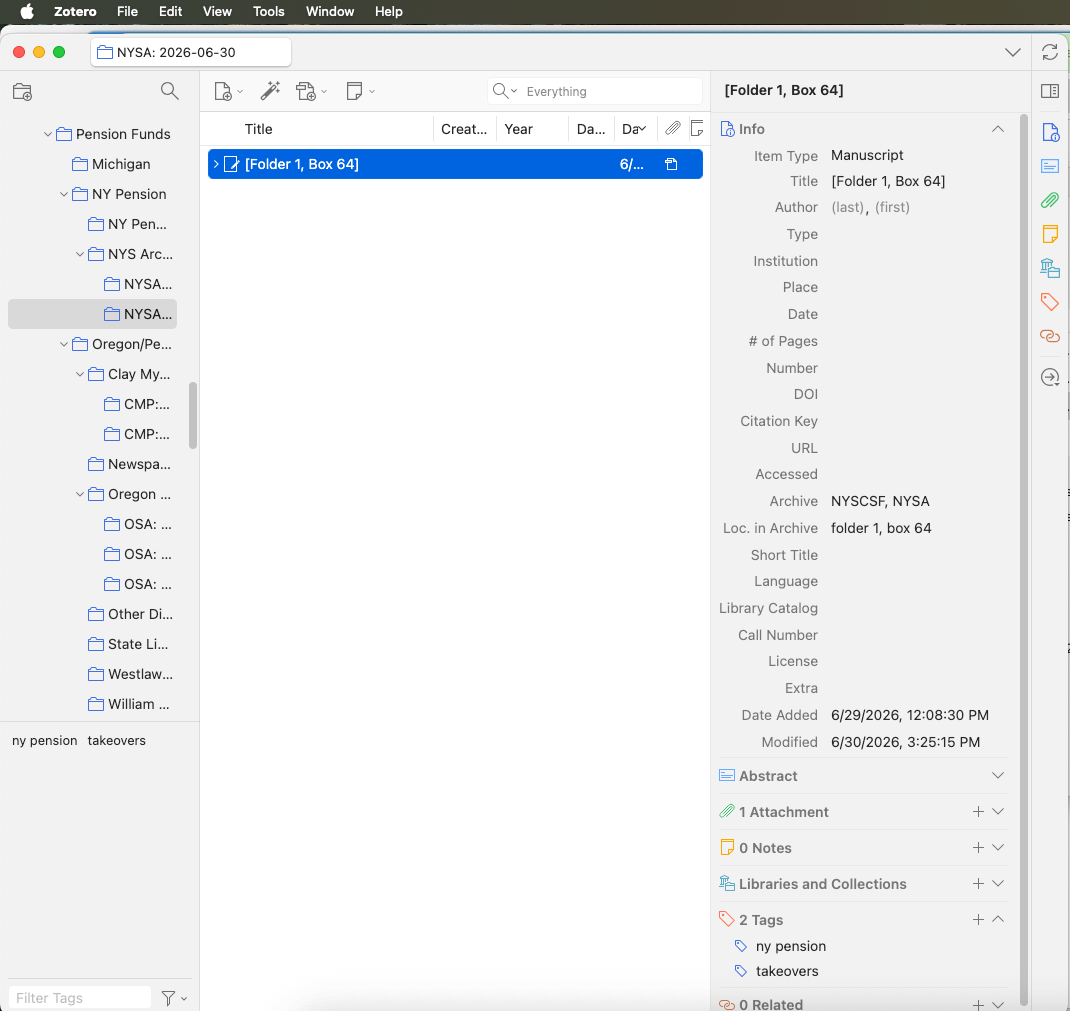
In my Zotero library (I have a different folder, called a “subcollection,” for each day at each archive), I create a manuscript-type item (an item is an entry in the Zotero database, which can have a PDF and notes attached to it) and give it the name of the folder and box number, in brackets (the brackets make it easy for the AI to identify later). “Manuscript” is basically Zotero’s default item type for an archival document. Then I add the folder and box number to the “Loc. in Archive” field and the abbreviation for the archive (in this case, it stands for “New York State Comptroller Subject Files, New York State Archives). This is important: it’s how I’m able to later cite all these documents! You don’t need to add the folder to Zotero now, but I like to just as an extra step to make sure nothing gets lost in the AI parsing process. Just make sure you label the PDF or folder with your scanned folder images with the folder, box, and archive citation information.
Finally, I like to use tags to organize items in Zotero. When I was scanning this folder, I saw that everything in it pertained to the NYS pension funds and to corporate takeovers, so I added those tags to the folder item. When AI extracts the individual documents, it will automatically copy these tags to each of them. This is the core reason to use a database like Zotero: a year from now, if I want to revise my chapter draft and add more on New York, I can instantly pull up every archival document, journal article, newspaper article from Proquest etc with the “ny pension” tag and then sort by date, author, other tags, etc. I can forget about a source, but Zotero remembers.
Anyway, this is what it looks like when I’ve finished adding folder 1, box 64 to Zotero:
Step 4
Repeat this for every folder of every box that I look at which is useful for me. Then when I get home…
Step 5: Run my “Zotero-split-scans” AI skill
This is where the magic happens. Using Claude Code, I created a “skill”—basically, a package of ready-made prompts and scripts—that allows Claude to take this PDF of a whole folder worth of scans and turn it into discrete PDFs and Zotero items for each document. All it took was a $20/month Claude Pro subscription and some back and forth in Claude Code telling it what I wanted the skill to do. Here’s how it works:
Download my zotero-split-scans skill from Github and follow the instructions on how to install it in Claude Code or ChatGPT Codex). You will need to have the Python coding language installed on your computer (you won’t need to actually write any code, though), and you will need to generate an API key for Zotero, which is basically a password that allows Claude to do things in your Zotero library. You can also use an AI coding agent to adapt this skill to your own workflow so it can talk to, say, Obsidian or Tropy or DevonTHINK. The skill is just some Python scripts and instructions to Claude on how to use them.
Fire up Claude Code and tell it to run the zotero-split-scans skill on the Zotero item created in Step 3:
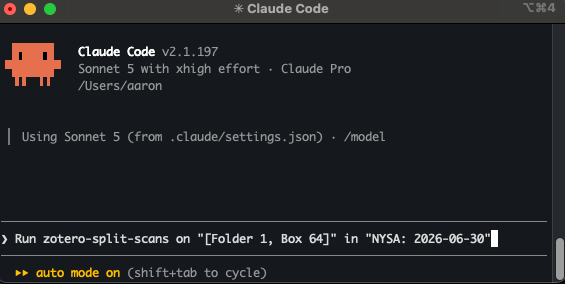
Claude gets to work. First, it finds the “Folder 1, Box 64” entry in Zotero (“NYSA: 2026-06-30” is the subcollection it’s in). Then it extracts the images from the PDF and makes judgements about which pages are part of the same document.
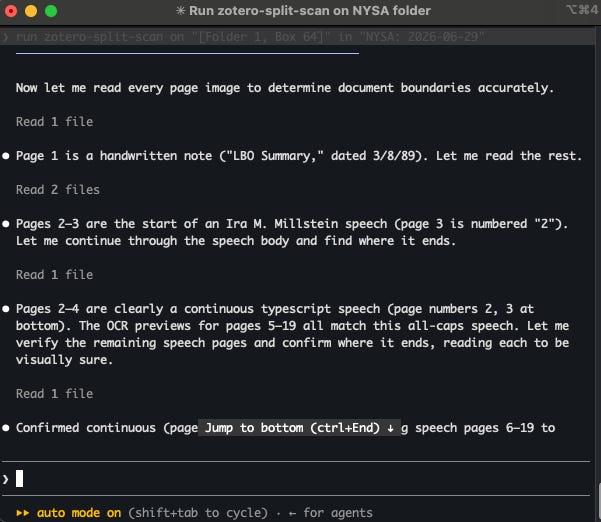
When it’s done, Claude creates a summary of how it plans to segment the folder
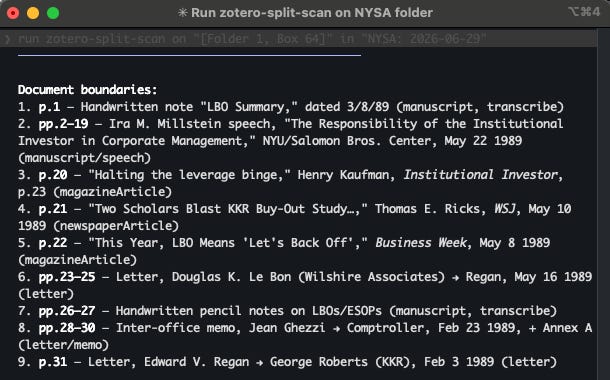
The skill is designed to categorize documents as either newspaper articles, magazine articles, letters (the Zotero item type for any form of correspondence), or manuscript (everything else). That’s just based on the types of documents that are normally in my archives.
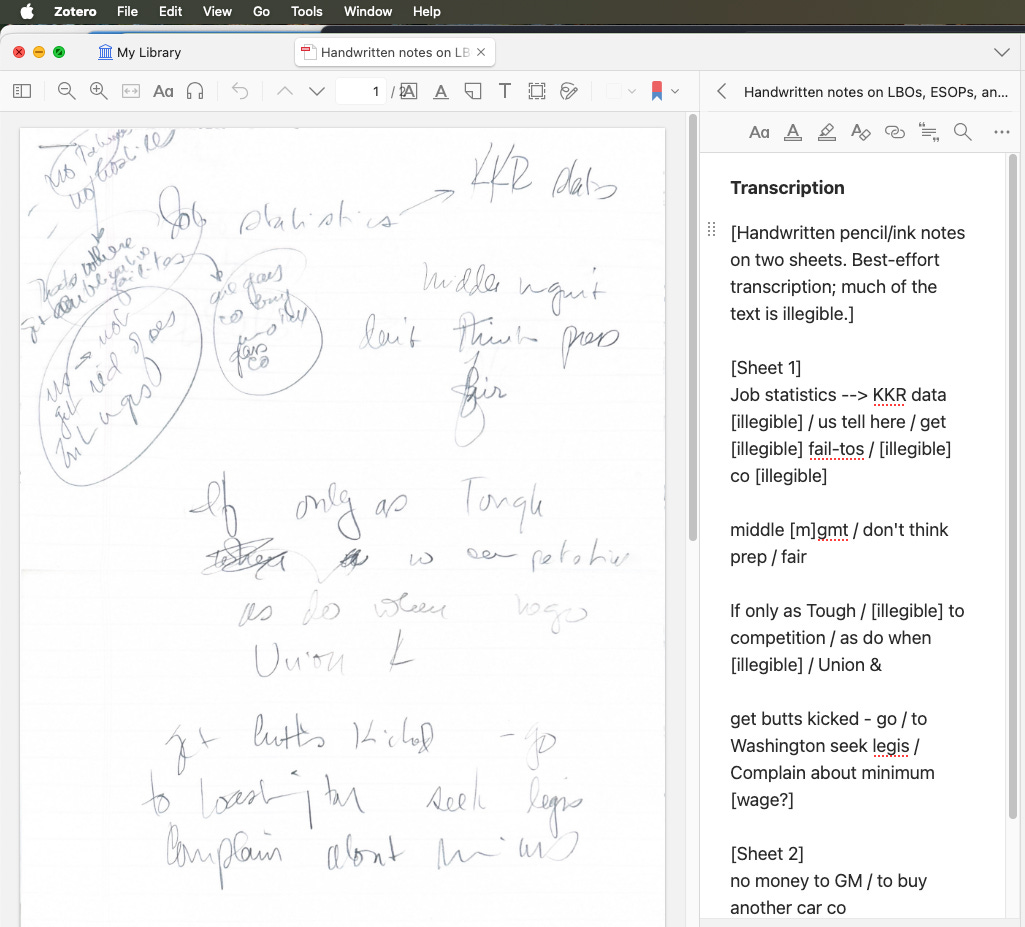
I also set up this skill so Claude would detect handwriting and add, as an attached note in Zotero, its own transcription. OCR is basically useless with handwriting, and while LLMs are not full-proof, it’s really helpful to have their best effort transcript on hand when reviewing handwriting.
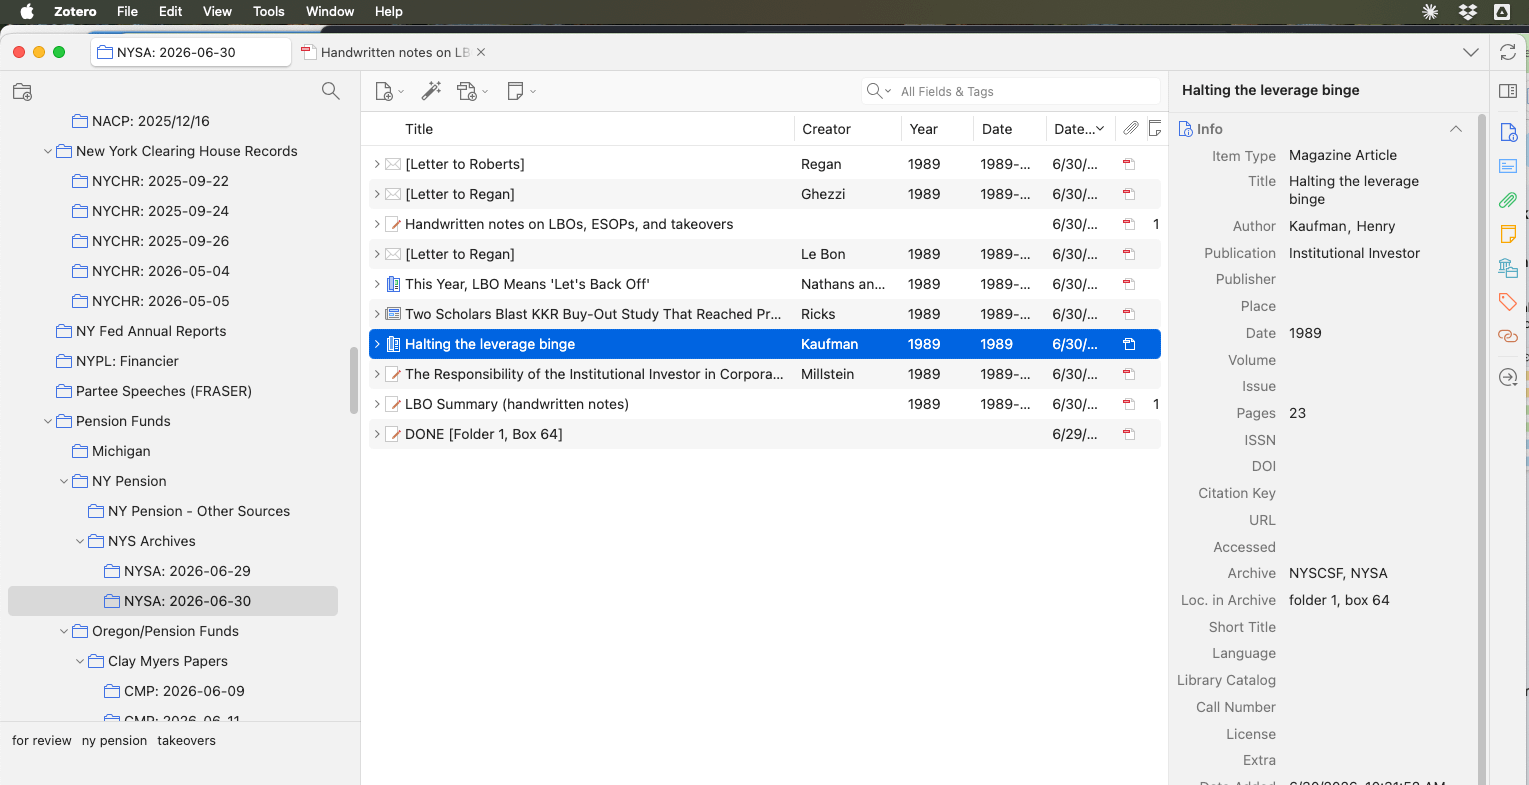
Claude creates the new PDF files and items in Zotero, adding the relevant metadata (including copying the archive tags I manually added to the folder scan in Step 3). It does a self-check to verify no pages got dropped, and creates a file where I can verify how it segmented the folder. Back in my Zotero, the collection now looks like this:
The original folder scan is still here, but marked as DONE,. And now all the documents I scanned have been organized with metadata that I can search for in Zotero, whenever I want.
Here’s Claude’s attempt at transcribing some gnarly handwriting. Not that helpful, but better than nothing!
I haven’t caught any mistakes with this system yet, but even if I do, it’s easy to update the metadata. What’s important is that I get everything somewhat organized from the get-go. Even if a document isn’t useful for me right now, it’ll be easy to find later if I want to come back to it. For example, If I want to write a standalone article on Henry Kaufman in a few years, I’ll be able to instantly summon all the relevant sources, without needing to wade through disorganized notes or photos.
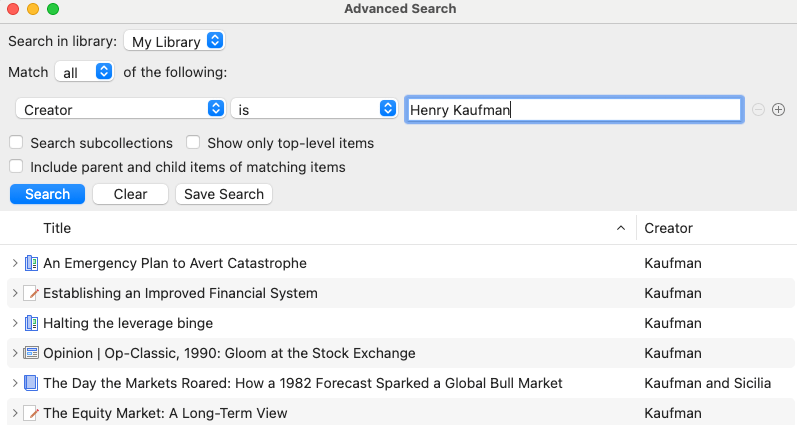
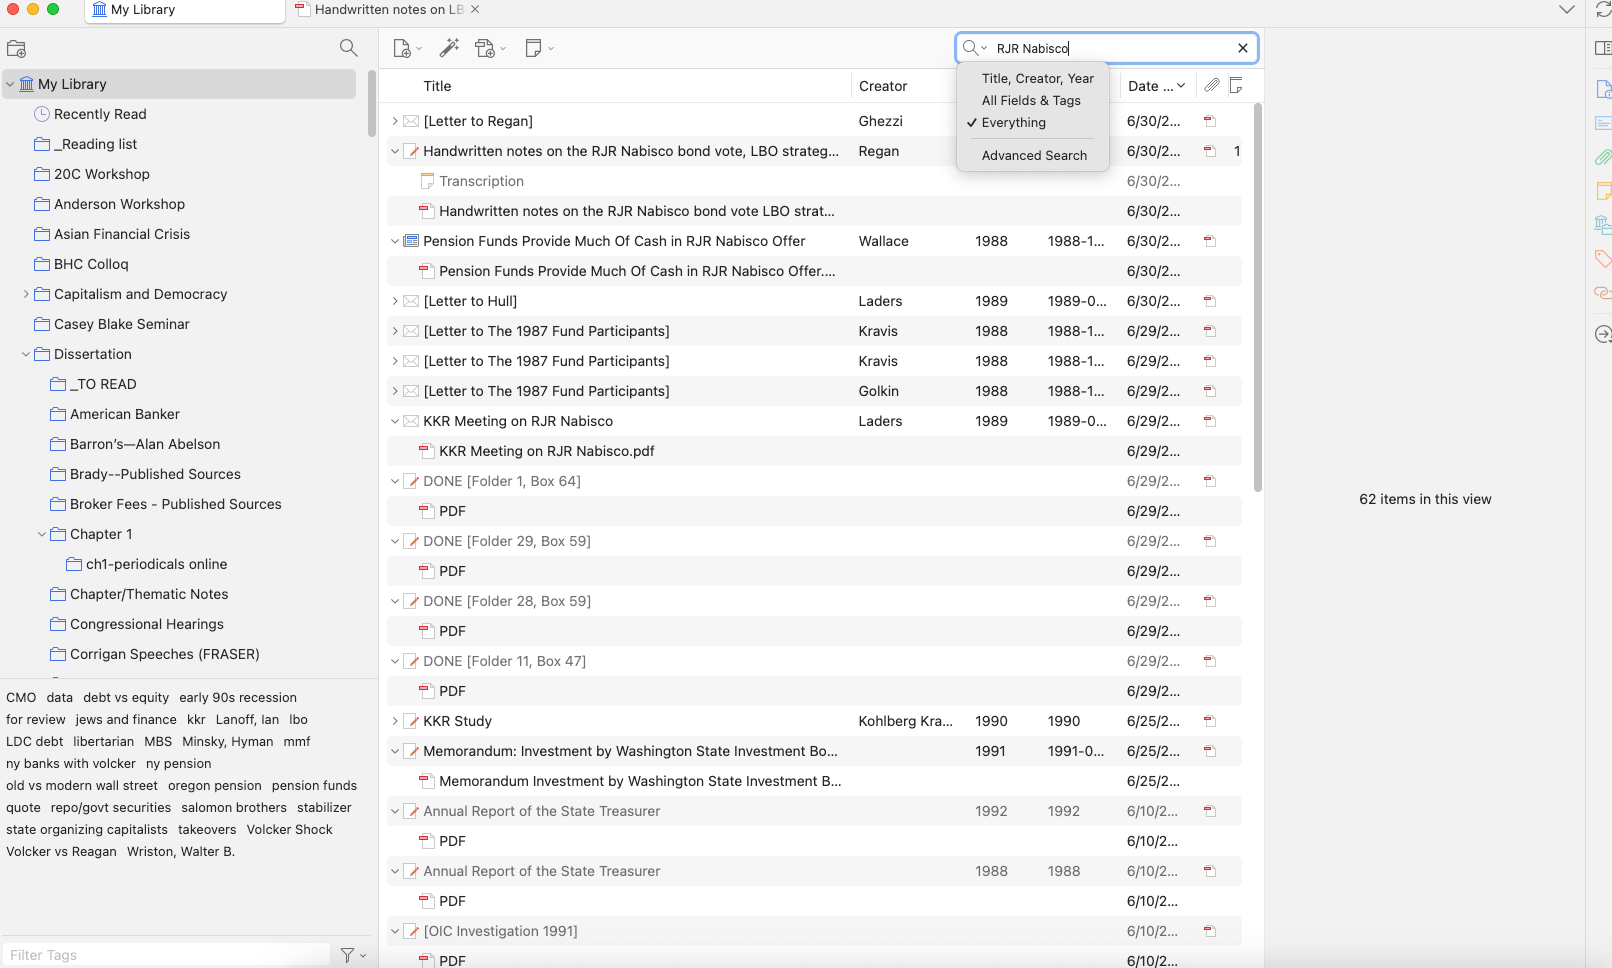
And because all the documents have been OCRed, I can even use Zotero to search the full text of everything in my library for a particular phrase, even if it’s not in metadata or tagged:
Step 6: Be a Historian
Now that the busywork is out of the way, I have a dissertation to write!
Aaron Freedman is a PhD Candidate in History at Columbia University.

Hi Aaron! I felt like you should be able to do more of this directly within Tropy -- which after all we designed specifically for working with archival documents -- so I created a Tropy plugin inspired by your workflow that segments batches of photos (e.g. cartons, folders) according to some empirically derived heuristics. Let me know what you think!
https://github.com/stakats/tropy-plugin-segment
This is super useful! Thank you